Entropy III: Shannon’s Theorem
Reliable communication over a noisy channel · Lecture 23
CS 574 · University of Illinois, Urbana-Champaign · Fall 2026
How much information survives noise?
Every transmitted bit is independently flipped with probability \(p\).
We can add redundancy to protect a message.
How many information bits can we send per channel bit?
The answer is governed by the entropy of the noise.
Today’s route
| Step | Main idea | Minutes |
|---|---|---|
| Model and theorem | Rate versus error | 12 |
| Random code and decoder | Typical Hamming rings | 13 |
| Bound the error | Concentration and counting | 30 |
| Protect every message | Discard the bad half | 15 |
| Capacity | Interpret both directions | 5 |
The binary symmetric channel
For input \(x=(x_1,\ldots,x_n)\), the output is
\[R=x\oplus Z,\qquad Z_j\sim\operatorname{Bernoulli}(p),\]
where the \(Z_j\) are independent and \(\oplus\) is bitwise XOR.
Thus \(\Pr[R_j\ne x_j]=p\), independently for every position.
We work with a fixed \(0<p<1/2\).
Encoding and decoding
\[\{0,1\}^k\ \xrightarrow{\ E\ }\ \{0,1\}^n \ \xrightarrow{\ \text{channel}\ }\ \{0,1\}^n \ \xrightarrow{\ D\ }\ \{0,1\}^k.\]
The sender transmits \(E(m)\); the receiver computes \(D(R)\).
For message \(m\), an error is the event \(D(R)\ne m\).
Our decoder may declare failure; a declared failure counts as an error.
Rate and reliability
\[\text{rate}=\frac{k}{n} \quad\text{information bits per transmitted bit}.\]
For a fixed block length \(n\), we want a large \(k\) and a small error probability.
The strongest guarantee protects every \(k\)-bit message.
The entropy of one noise bit
\[H(p)=-p\lg p-(1-p)\lg(1-p).\]
Here \(\lg\) means logarithm to base \(2\), and \(0\lg0=0\).
For \(0<p<1/2\), \(H(p)\) is continuous and increasing.
About \(2^{nH(p)}\) noise patterns matter on the exponential scale.
The capacity threshold
\[\boxed{C=1-H(p).}\]
Below \(C\), arbitrarily small error is possible for long enough blocks.
Above \(C\), even average success tends to zero.
This is a limit on information rate under independent random noise.
Shannon’s theorem: achievable rates
Fix \(0<p<1/2\), a rate gap \(\delta>0\), and an error target \(0<\gamma<1\).
For sufficiently large \(n\), if
\[k\leq n\bigl(1-H(p)-\delta\bigr),\]
there are encoding and decoding functions with
\[\Pr[D(R)\ne m\mid m\text{ sent}]\leq\gamma \qquad\text{for every }m.\]
Shannon’s theorem: the converse
Fix \(0<p<1/2\), \(\delta>0\), and \(0<\gamma<1\).
For sufficiently large \(n\), if
\[k\geq n\bigl(1-H(p)+\delta\bigr),\]
then every encoder and decoder satisfy
\[\Pr[D(R)=M]<\gamma, \qquad M\text{ uniform on }\{0,1\}^k.\]
We state this direction without proof, as in the notes.
Read the quantifiers carefully
| Below capacity | Above capacity |
|---|---|
| There exists a code | Every code is constrained |
| Every input message | A uniform random input message |
| Error can be arbitrarily small | Success must become arbitrarily small |
The theorem allows the block length to depend on \(p,\delta,\gamma\).
The achievability proof in three moves
- Sample twice as many codewords as we need.
- Show that the average decoding error is small.
- Retain the half with the smallest error probabilities.
The final step turns an average guarantee into a guarantee for every message.
Distance counts flipped bits
\[\Delta(x,r)=\bigl|\{j:x_j\ne r_j\}\bigr|.\]
If \(x\) is sent, then \(\Delta(x,R)\) has distribution
\[\operatorname{Binomial}(n,p),\qquad \mathbb E[\Delta(x,R)]=np.\]
Typical received words lie near distance \(np\) from the transmitted word.
A typical Hamming ring
Choose a small constant \(0<\varepsilon<1\).
\[\mathcal R(x)=\{r\in\{0,1\}^n: (1-\varepsilon)np\leq\Delta(x,r)\leq(1+\varepsilon)np\}.\]
The ring consists of the plausible received words for \(x\).
Also require \((1+\varepsilon)p<1/2\).
The rings of error
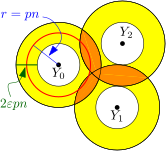
The red curve marks distance \(np\); the ring has width \(2\varepsilon np\).
The typical-ring decoder
Given the received word \(r\), inspect every codeword.
If exactly one codeword \(Y_i\) satisfies \(r\in\mathcal R(Y_i)\), output its index.
If none or more than one qualify, declare failure.
Being too close to a codeword can also put \(r\) outside its ring.
Two ways to lose the message
Atypical noise: \(R\notin\mathcal R(Y_i)\).
Ambiguity: \(R\in\mathcal R(Y_i)\) and also lies in another codeword’s ring.
We will control the first event by concentration and the second by counting.
Sample a larger codebook
Set \(N=2^{k+1}\), where \(k\leq n(1-H(p)-\delta)\).
Sample \(Y_0,\ldots,Y_{N-1}\) independently and uniformly from \(\{0,1\}^n\).
Analyze the ring decoder using all \(N\) codewords.
Eventually retain only \(2^k\) of them.
The randomness is used to prove that a good fixed codebook exists.
What kind of construction is this?
There are exponentially many candidate codewords.
The decoder scans the codebook, and selecting the best half requires evaluating error probabilities.
This is an existence proof. It does not provide a computationally efficient coding algorithm.
Deleting competitors can only help
Suppose \(r\) uniquely decodes to \(Y_i\).
If we delete other codewords but keep \(Y_i\), then \(r\) still uniquely decodes to \(Y_i\).
Hence deleting competitors never increases the decoding error of a retained word.
This is why we may analyze a larger codebook first.
Two sources of randomness
| Random choice | What it determines |
|---|---|
| Codebook \(Y_0,\ldots,Y_{N-1}\) | Which strings represent messages |
| Independent channel noise | Which word is received |
First fix a codebook and measure its channel error.
Then average that error over randomly sampled codebooks.
The channel weight of a received word
For a fixed transmitted word \(x\) and received word \(r\), define
\[w(x,r)=p^{\Delta(x,r)}(1-p)^{n-\Delta(x,r)}.\]
This is \(\Pr[R=r\mid x\text{ sent}]\).
\[\sum_{r\in\{0,1\}^n}w(x,r)=1.\]
Successful decoding regions
For a fixed codebook, let
\[S_i=\mathcal R(Y_i)\setminus\bigcup_{j\ne i}\mathcal R(Y_j).\]
These are exactly the received words that decode uniquely to index \(i\).
The regions \(S_i\) are pairwise disjoint; the rings need not be.
Error for one indexed codeword
\[W_i=\Pr[R\notin S_i\mid Y_i\text{ sent}] =\sum_r w(Y_i,r)\,\mathbf1_{\{r\notin S_i\}}.\]
For a fixed codebook, \(W_i\) is a number in \([0,1]\).
For a random codebook, \(W_i\) is a random variable.
Our goal is \(\mathbb E_{\mathcal C}[W_i]\leq\gamma/4\) for every index \(i\).
First error: atypical noise
Fix the transmitted codeword \(Y_i=x\) and set \(Z=\Delta(x,R)\).
\[Z=\sum_{j=1}^n\mathbf1_{\{x_j\ne R_j\}}, \qquad\mathbb E[Z]=np.\]
Missing the ring means \(|Z-np|>\varepsilon np\).
This event does not depend on the competing codewords.
Concentration puts the output in the ring
The two-sided Chernoff bound gives, for \(0<\varepsilon<1\),
\[\Pr[R\notin\mathcal R(x)] \leq 2\exp\!\left(-\frac{\varepsilon^2pn}{4}\right).\]
For fixed \(p,\varepsilon>0\), this decays exponentially with \(n\).
The estimate is uniform in the transmitted word \(x\).
Reserve a budget for atypical noise
Choose \(n\) large enough that
\[a_n:=2\exp\!\left(-\frac{\varepsilon^2pn}{4}\right) \leq\frac{\gamma}{8}.\]
Then the probability mass outside any transmitted word’s ring is at most \(\gamma/8\).
Second error: a competing explanation
Now suppose \(Y_i=x\) and a particular \(r\in\mathcal R(x)\) is received.
The decoder fails exactly when some \(j\ne i\) satisfies
\[r\in\mathcal R(Y_j).\]
We need a bound that holds for each fixed pair \((x,r)\).
Freeze the transmitted and received words
Condition on \(Y_i=x\) and \(R=r\) when index \(i\) is sent.
Each other codeword \(Y_j\) is still uniform on \(\{0,1\}^n\).
The other codewords are independent of \(Y_i\) and its channel noise.
This leaves a simple counting problem for every competitor.
Reverse the ring relation
Hamming distance is symmetric, so
\[r\in\mathcal R(Y_j) \quad\Longleftrightarrow\quad Y_j\in\mathcal R(r).\]
Instead of moving a random ring, keep the ring around \(r\) fixed and sample its center candidate \(Y_j\).
One uniform competitor
\[\Pr[Y_j\in\mathcal R(r)] =\frac{|\mathcal R(r)|}{2^n}.\]
All strings are equally likely as a sampled codeword.
The number of strings in a Hamming ring is independent of its center.
Count the distance layers
There are \(\binom nm\) strings at Hamming distance \(m\) from \(r\).
\[|\mathcal R(r)| =\sum_{m=\lceil(1-\varepsilon)np\rceil}^{\lfloor(1+\varepsilon)np\rfloor}\binom nm.\]
Put \(q=(1+\varepsilon)p<1/2\).
The largest binomial coefficient in this range is at \(m=\lfloor nq\rfloor\).
Recall the entropy counting bound
For \(0\leq q\leq1/2\), the previous lecture gives
\[\binom n{\lfloor nq\rfloor}\leq2^{nH(q)}.\]
At most \(n+1\) distance layers occur in any sum.
Thus an entropy estimate controls the whole ring.
The size of one ring
Combining the layer count and the entropy bound,
\[|\mathcal R(r)| \leq(n+1)\binom n{\lfloor nq\rfloor} \leq(n+1)2^{nH(q)},\]
where \(q=(1+\varepsilon)p<1/2\).
The polynomial factor \(n+1\) will be dominated by an exponential rate gap.
A competitor hits with small probability
For any fixed \(r\) and any \(j\ne i\),
\[\Pr[Y_j\in\mathcal R(r)] \leq(n+1)2^{-n(1-H(q))}.\]
There are \(N-1=2^{k+1}-1\) possible competitors.
We need the combined probability of any hit.
Union bound over competing codewords
For fixed \(x\) and \(r\in\mathcal R(x)\), let \(b_{i,r}\) be the conditional ambiguity probability.
\[\begin{aligned} b_{i,r} &\leq\sum_{j\ne i}\Pr[Y_j\in\mathcal R(r)]\\ &\leq2^{k+1}(n+1)2^{n(H(q)-1)}. \end{aligned}\]
No independence between the ambiguity events is needed for this union bound.
Insert the rate bound
Since \(k\leq n(1-H(p)-\delta)\),
\[\begin{aligned} b_{i,r} &\leq2^{k+1}(n+1)2^{n(H(q)-1)}\\ &\leq2(n+1)2^{n(H(q)-H(p)-\delta)}. \end{aligned}\]
We want the exponent to be a negative constant times \(n\).
Spend half the rate gap on the ring width
By continuity of \(H\), choose \(\varepsilon>0\) small enough that
\[q=(1+\varepsilon)p<\frac12, \qquad H(q)-H(p)\leq\frac\delta2.\]
Also keep \(\varepsilon<1\). Then
\[H(q)-H(p)-\delta\leq-\frac\delta2.\]
Exponential decay beats the layer count
\[b_{i,r}\leq b_n:=2(n+1)2^{-n\delta/2}.\]
For fixed \(\delta>0\), \(b_n\to0\).
Increase \(n\) until \(b_n\leq\gamma/8\).
This bound holds for every \(i\), every \(x\), and every \(r\in\mathcal R(x)\).
The conditional collision bound
Given \(Y_i=x\) and any received word \(r\in\mathcal R(x)\),
\[\Pr_{\mathcal C\setminus Y_i}[r\notin S_i\mid Y_i=x] \leq\frac\gamma8.\]
Only the other codewords are random in this statement.
Next, average over the actual channel output distribution.
Average with the channel weights
For \(Y_i=x\), the inside-ring contribution is
\[g(x)=\sum_{r\in\mathcal R(x)} w(x,r)\Pr_{\mathcal C\setminus Y_i}[r\notin S_i\mid Y_i=x].\]
Each term keeps its weight \(w(x,r)\).
These weights turn a sum over received strings into a probability.
Inside the ring: total error mass
Apply the pointwise collision bound to every summand:
\[\begin{aligned} g(x) &\leq\sum_{r\in\mathcal R(x)}w(x,r)\frac\gamma8\\ &\leq\frac\gamma8, \end{aligned}\]
because \(\sum_{r\in\mathcal R(x)}w(x,r)\leq1\).
Outside the ring: total error mass
Outside \(\mathcal R(x)\), the ring decoder cannot return index \(i\).
\[f(x)=\sum_{r\notin\mathcal R(x)}w(x,r) \leq a_n\leq\frac\gamma8.\]
This contribution is fixed once \(Y_i=x\) is fixed.
Competing codewords do not affect it.
Combine the two error contributions
\[\begin{aligned} \mathbb E_{\mathcal C}[W_i\mid Y_i=x] &=f(x)+g(x)\\ &\leq\frac\gamma8+\frac\gamma8 =\frac\gamma4. \end{aligned}\]
The estimate holds for every transmitted word \(x\).
Remove the conditioning
Average over the uniform choice of \(Y_i\):
\[\mathbb E_{\mathcal C}[W_i] =\mathbb E_{Y_i}\!\left[ \mathbb E_{\mathcal C}[W_i\mid Y_i]\right] \leq\frac\gamma4.\]
Every index has small expected error over random codebooks.
We still need one fixed codebook protecting every retained index.
Average the errors of all codewords
Let \(\overline W=N^{-1}\sum_{i=0}^{N-1}W_i\), with \(N=2^{k+1}\).
\[\mathbb E_{\mathcal C}[\overline W] =\frac1N\sum_{i=0}^{N-1}\mathbb E_{\mathcal C}[W_i] \leq\frac\gamma4.\]
Linearity of expectation applies even though the \(W_i\) are dependent.
Fix one good codebook
Some sampled codebook satisfies
\[\overline W\leq\frac\gamma4, \qquad\text{so}\qquad \sum_{i=0}^{N-1}W_i\leq\frac{N\gamma}{4}.\]
Otherwise every codebook would have average error greater than its expectation bound.
From now on, the codebook is fixed.
How many codewords can be bad?
Let \(B=\{i:W_i>\gamma\}\).
\[\gamma|B|\leq\sum_{i\in B}W_i \leq\sum_{i=0}^{N-1}W_i \leq\frac{N\gamma}{4}.\]
Thus \(|B|\leq N/4\); at least \(3N/4\) indices have \(W_i\leq\gamma\).
We need only \(N/2=2^k\) good indices.
Keep the best half
Retain the \(2^k\) indices with the smallest \(W_i\).
Call their codewords \(X_0,\ldots,X_{2^k-1}\).
Every retained index had error at most \(\gamma\) in the larger codebook.
Discarding codewords with large error is called expurgation.
Recompute the decoder on the retained set
The new decoder searches only \(X_0,\ldots,X_{2^k-1}\).
For each retained index,
\[S_i^{\mathrm{old}}\subseteq S_i^{\mathrm{new}}, \qquad W_i^{\mathrm{new}}\leq W_i^{\mathrm{old}}\leq\gamma.\]
Removing competitors can turn ambiguous outputs into uniquely decodable outputs.
Assign the messages
Choose a bijection between the \(2^k\) messages and the retained codewords.
Encode each message with its assigned word.
Decode by the unique-ring rule on the retained set.
The guarantee now applies to every \(k\)-bit message.
Why the retained words are distinct
Suppose two sampled indices had the same word: \(Y_i=Y_j\).
Their rings coincide, so neither index ever decodes uniquely.
Thus \(W_i=W_j=1\) in the original codebook.
Since \(\gamma<1\), no such index belongs to the selected good half.
Achievability is proved
For \(k\leq n(1-H(p)-\delta)\) and sufficiently large \(n\),
\[\boxed{\max_m\Pr[D(R)\ne m\mid m\text{ sent}]\leq\gamma.}\]
Random coding controls average error.
Expurgation makes the guarantee hold for every message.
Choose the parameters in this order
- Fix the channel parameter \(0<p<1/2\).
- Fix \(0<\delta<1-H(p)\) and \(0<\gamma<1\).
- Choose \(\varepsilon\in(0,1)\) with \(q=(1+\varepsilon)p<1/2\) and \(H(q)-H(p)\leq\delta/2\).
- Choose \(n\) so that both error bounds are at most \(\gamma/8\).
- Take an integer \(k\leq n(1-H(p)-\delta)\).
A quantitative view of the proof
Before choosing the final block length,
\[\mathbb E_{\mathcal C}[W_i] \leq\underbrace{2e^{-\varepsilon^2pn/4}}_{\text{atypical noise}} +\underbrace{2(n+1)2^{-n\delta/2}}_{\text{ambiguity}}.\]
A smaller rate gap leaves less room for noise fluctuations.
A longer block makes both sources of error small.
Where the capacity expression comes from
\[\underbrace{2^k}_{\text{messages}} \cdot\underbrace{2^{nH(p)}}_{\text{typical noise scale}} \quad\text{versus}\quad \underbrace{2^n}_{\text{possible received words}}.\]
The threshold on the exponential scale is \(k/n=1-H(p)\).
The proof makes this intuition precise using a slightly wider ring and a fixed rate gap.
The rings may overlap
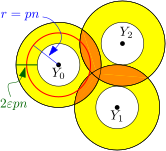
We control the probability of ambiguity, not the absence of intersections.
Random noise is part of the theorem
The channel flips bits independently with probability \(p\).
The theorem bounds failure probability over that noise.
It does not assert correct decoding for every pattern of roughly \(np\) flips.
“Every message” and “every noise pattern” are different guarantees.
Why there is also a converse
Each message needs a decoding region carrying substantial channel probability.
Different messages have disjoint decoding regions inside a space of \(2^n\) received words.
Typical noise spreads probability over roughly \(2^{nH(p)}\) possible outputs per message.
This motivates the threshold \(1-H(p)\); it is packing intuition, not a proof of the strong converse.
Scope and the noiseless endpoint
At \(p=0\), \(H(0)=0\): transmit \(k\leq n\) bits directly with zero error.
If \(k>n\), only \(2^n\) distinct received words are possible, so uniform-message success is at most \(2^{n-k}\).
The ring proof handles fixed \(0<p<1/2\); the endpoint follows directly by counting.
Three ideas to remember
Concentration: the received word lies in a typical ring.
Entropy counting: a random competing codeword rarely explains it.
Expurgation: average reliability yields reliability for every retained message.
Together they achieve every fixed rate below \(1-H(p)\).
Reading
Notes 45: Entropy III — Shannon’s Theorem.
The notes follow Michael Mitzenmacher and Eli Upfal, Probability and Computing (2005), §§9.1–9.3.
Prerequisites: entropy, binomial coefficient estimates, Chernoff bounds, and the probabilistic method.
CS 574 · Lecture 23 · Entropy III