Nondeterministic Finite-State Automata
In order to prove Kleene’s theorem, we need to introduce yet another model of computation for regular languages to act as an intermediary between DFAs and regular expressions. This model is strictly more expressive than DFAs, making it possible to prove regularity of a language more easily than designing a DFA or a regular expression. The expressivity will also serve us well next week when we discuss taking regular languages and applying transformations to create new provably regular languages.
The idea behind the new model is to add the power of choice to DFAs. We’ll still have a finite set of states and read symbols from a string from beginning-to-end, but when reading a symbol, we get to nondeterministically choose which state to go to next. We get to guess, which of several possible transitions might lead us to an accept state. If any sequence of choices consistent with the input string leads to an accept state, then we accept the string. The members of this model are called nondeterministic finite-state automata (NFAs).
For example, the transition graph below represents an NFA that accepts all strings containing either 00 or 11 (inclusive) as a substring.
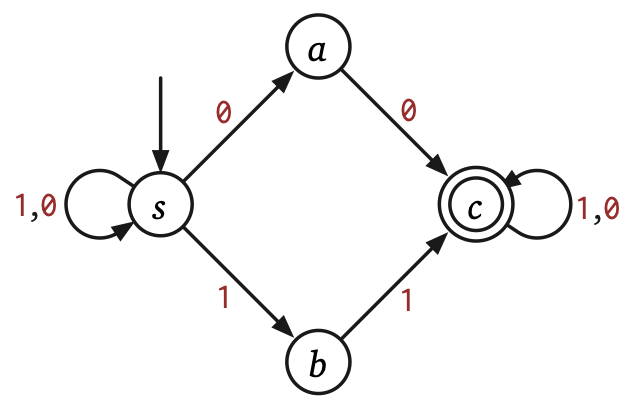
You have to read in a substring 00 to go from s to c through a. You have to read in a substring 11 to go from s to c through b. But you have the option of staying parked on s until one of those two substrings appear, so the NFA accepts the correct language. For example, the string 0101001 could go through state transitions s \xrightarrow{0} s \xrightarrow{1} s \xrightarrow{0} s \xrightarrow{1} s \xrightarrow{0} a \xrightarrow{0} c \xrightarrow{1}, so it would be accepted.
Formal definition
Formally, a nondeterministic finite-state automaton (NFA) M = (\Sigma, Q, \delta, s, A) has five components:
- An arbitrary finite input alphabet \Sigma
- An arbitrary finite set of states Q
- An arbitrary transition function that takes a state and symbol and go to a subset of states \delta: Q \times \Sigma \to 2^Q. Here, 2^Q is mnemonic notation for the powerset of Q, the set of all subsets of Q. You may have seen \mathcal{P}(Q) used instead. This function may even evaluate to \varnothing.
- A start state s \in Q
- A subset of accepting states A \subseteq Q
In the formal definition, NFAs read in symbols one at a time from a string w \in \Sigma^*, but instead of maintaining a single current state, they maintain a whole set of current states initially starting with \{s\}. The subset being maintained is the entire subset of states that could be reached via nondeterminsitic choices consistent with the symbols being read. When the NFA reads a symbol a, it applies the transition function to every member of the subset of current states, and it goes the union of all the results. In particular, if the set of current states ever goes empty, then it stays empty forever. After reading all of w, the NFA accepts w if any of the current states are accepting. It rejects w otherwise.
Like with DFAs, we can define an extended transition function \delta^* : Q \times \Sigma^* \to 2^Q which takes a single state and a string and goes to a set of states as follows: \delta^*(q, w) := \begin{cases} \{q\} &\text{if $w = \varepsilon$}\\ \bigcup_{r \in \delta(q, a)} \delta^*(r, x) &\text{if $w = ax$}. \end{cases} In other words, we ask, “Where would all the states in \delta(q, a) ultimately take us if we kept reading the symbols from x?” The NFA accepts w if and only if \delta^*(s, w) \cap A \neq \varnothing, and it rejects w otherwise. Its language is the set of strings it accepts: L(M) := \{w \mid \delta^*(s, w) \cap A \neq \varnothing\}
Common extensions
There are two common extensions to the standard definition of NFAs that make them easier to design without actually changing the set of languages they can accept.
The first is based on the observation that NFAs always maintain arbitrary subsets of states as they read in the input string.
So why, then, are we restricting ourselves to start with exactly one state?
For example, this (one) NFA has two start states.
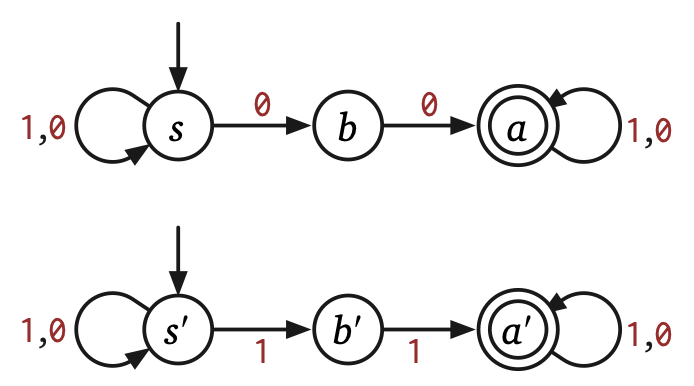
We can interpret a run of the NFA as nondeterministically choosing one of the start states and then nondeterministically doing transitions as discussed before. Formally, an NFA with start states S \subseteq Q accepts w if and only if (\bigcup_{s \in S} \delta^*(s, w)) \cap A \neq \emptyset.
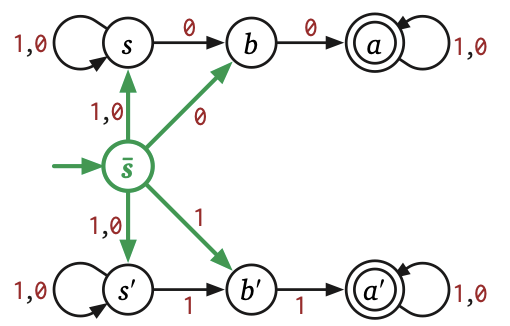
Again, it’s no more powerful than what we’ve seen already. Given an NFA with multiple start states S, we can construct one with a single start state by
- adding a new state \bar{s},
- copying all outgoing transitions from S to leave \bar{s} instead,
- declaring \bar{s} to be an accepting state if and only if S contains an accepting state,
- and declaring \bar{s} as the one start state.
Here’s what happens to the two start state NFA:
The second common extension is to allow for \varepsilon-transitions that allow the machine to change state without having to read an input symbol.
For example, this silly machine still accepts the same language as last time:
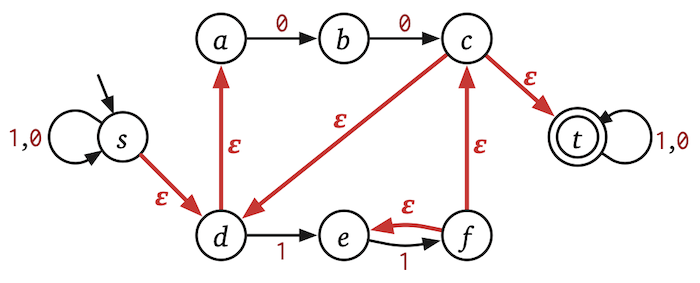
In the intuition of guessing a path through the NFA, you can optionally take any \varepsilon-transition you’d like leaving your current state. Formally, we redefine the transition function as \delta: Q \times (\Sigma \cup \{\varepsilon\}) \to 2^Q. Let \varepsilon\text{-reach}(q) for a state q \in Q be the set of states reachable by a sequence of \varepsilon-transitions. In other words, if we consider the graph G of NFA states and \varepsilon-transitions between them, the \varepsilon\text{-reach}(q) is exactly the set of vertices r for which there is a path from q to r. Then, \delta^*(p, w) := \begin{cases} \varepsilon\text{-reach}(p) &\text{if $w = \varepsilon$}\\ \bigcup_{r \in \varepsilon\text{-reach}(p)} \bigcup_{q \in \delta(r, a)} \delta^*(q, x) &\text{if $w = ax$}. \end{cases} In other words, grab all the states you can reach via 0 or more \varepsilon-transitions, read a symbol, and recurse.
\varepsilon-transitions can be very convenient for constructing NFAs, but (again) they don’t actually makes NFAs any more powerful! Given an NFA M = (Q, \delta, S, A) with \varepsilon-transitions and multiple start states, we can make a new one without \varepsilon-transitions.1 In short, if q \in \varepsilon\text{-reach}(p), then we add all actual symbol transitions out of q to leave p instead. Additionally, we update the accept states to include any state q with an accept state within its \varepsilon\text{-reach}.
TODO: Make a figure.
More formally, we make a new NFA M' = (Q, \delta', S, A') from M where
- \delta'(p, a) = \bigcup_{q \in \varepsilon\text{-reach}(p)} \delta(q, a) and
- A' = \{q \mid \varepsilon\text{-reach}(q) \cap A \ne \varnothing\}.
Note that I’m using a somewhat different construction than shown in Erickson’s Models 4 to (in my opinion) better match the above definition of \delta^* It also allows us to present \varepsilon-transitions before multiple start states with the latter presentation simplified, something I will do in future versions of these notes.
Kleene’s theorem
We’re now ready to sketch a proof of Kleene’s theorem that the languages accepted by DFAs are precisely the regular languages. The proof has two parts:
- Prove NFAs accept the same languages as DFAs
- Prove NFAs accept exactly the regular languages
NFAs accept all “automatic” languages and vice versa
It might feel like NFAs should be capable of accepting more languages than DFAs. After all, NFAs are like DFAs that let you try a bunch of different options at once, and its almost trivial to show NFAs accept at least as many languages. Indeed, consider any DFA M = (Q, \delta, s, A). The NFA M' = (Q, \delta', s, A) with \delta'(q, a) = \{\delta(q, a)\} accepts the same language as M.
However, any language accepted by an NFA can be accepted by a DFA after all. This fact is easiest to see by remembering the formal description of an NFA: at each moment in time, we have a current subset of states. We can build a DFA that models that idea by using these subsets as its states.
Suppose we have an NFA M = (Q, \delta, s, A) with one start state and no \varepsilon-transitions (again, those extensions only make NFAs more convenient to design, not more powerful.) We use a subset construction (or power-set construction) to build an equivalent DFA M' = (Q', \delta', s', A') where
- Q' = \mathcal{P}(Q)
- \delta'(P, a) = \bigcup_{q \in P} \delta(q, a)
- s' = \{s\}
- A' = \{P \subseteq Q \mid P \cap A \neq \emptyset\}
Here’s what happens when you apply the construction to same example NFA we started with.
Notice how the resulting DFA has a lot of states, most of which aren’t even reachable.
But hey, the set of states is still finite!
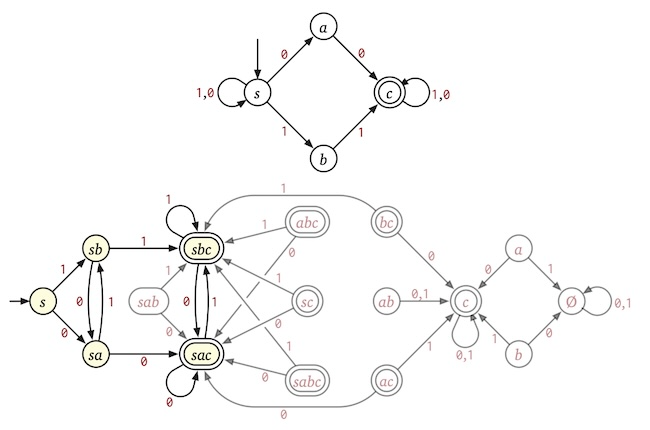
If we actually wanted to build something based on such a DFA in practice, we would want to throw away all the unreachable states. It’s also possible to avoid making them in the first place by essentially performing a breadth (or whatever)-first search of the reachable states in the result DFA from its start state. See Erickson’s Models 4.7 for details if you’re interested.
NFAs accept all regular languages
Going back and forth between regular expressions and NFAs takes a fair bit more work.
We’ll start with an algorithm by Thompson (1968) that turns any regular expression R into an NFA with \varepsilon-transitions that accepts the language L(R).
Even better; it creates an NFA with a certain convenient form.
The NFA has exactly one accept state, and that accept state is distinct from the NFA’s start state.
This form is convenient, because it makes it easier to take advantage of the recursive defintion of regular languages.
Given a regular expression consisting of an operation applied to one or two simpler subexpressions, we’ll recursively compute NFAs for the subexpressions and then combine them together by adding a handful of new transitions.
The details are easiest to explain with state transition graphs.
A recursively constructed NFA for the subexpression S will be depicted as follows:
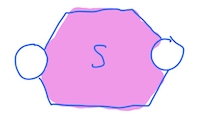
With the high level idea in place, it’s time to fill in the details. Given a regular expression R over the alphabet \Sigma:
- If R = \varnothing, we construct the following NFA:
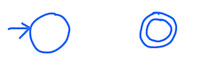
- If R = \varepsilon, we construct the following NFA:
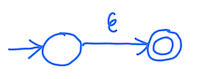
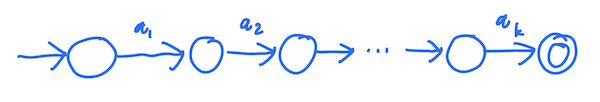
- If R = w with w = a_1 a_2 \dots a_k \in \Sigma^*$, we construct the following NFA that has us walk through a chain of simple transitions:
- If R = ST for subexpressions S and T, we construct the following NFA chaining together the recursively computed subexpressions NFAs:
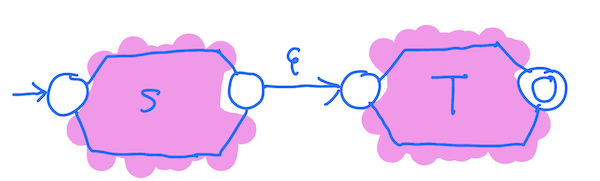 Note the \varepsilon-transition between S’s accept state and T’s start state. We cannot simply merge S’s accept state and T’s start state, because there may be some input strings matching S that require us to go through S’s accept state multiple times in order for S’s NFA to accept the string, so we have to guess when it’s time to start reading the T half the string.
- If R = S + T for subexpressions S and T, we construct the following NFA that lets us guess which subexpression’s NFA to go through:
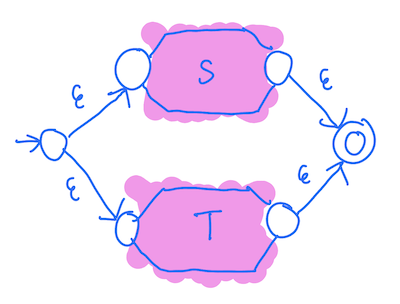 Here, we need the \varepsilon-transitions instead of identifying the two NFAs start and accept states, because we don’t want to read part of a string as if it matches S and then read the rest as if it matches T.
The \varepsilon-transitions force us to commit to one subexpression’s NFA.
- Finally, if R = S^* for some subexpression S, we construct the following NFA:
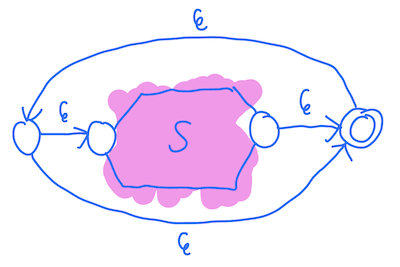 The \varepsilon-transitions for this NFA are used to make sure we really do start over every time we guess we’re about to read another substring matching S.
And that’s the algorithm.
It tends to result in rather complicated NFAs which are… also kind of pretty?
They remind me of series-parallel graphs and circuits (as they should given the concatenations and unions.)
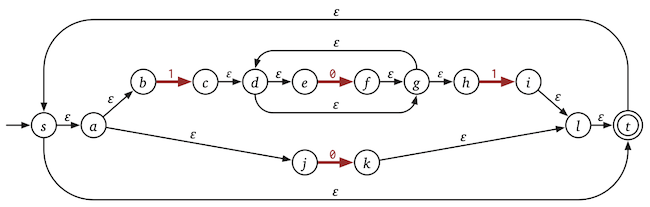
For example, (1 0^* 1 + 0)^* is accepted by the following NFA:
NFAs accept only regular languages
The final step in proving Kleene’s theorem is showing that every language accepted by an NFA is regular. Similar to last time, we’ll look at an algorithm for converting NFAs into equivalent regular expressions. The argument will be similar to the one originally used by Kleene (1951), but with a nicer formulation proposed by McNaughton and Yamada (1960).
We’ll build up a bit of intuition first. We started with regular NFAs without \varepsilon-transitions. In their state transition graphs, each edge is labeled with a single symbol a from the input alphabet. In order to follow the edge while reading in an input string ax, we have to remove the length-one prefix a from the beginning of the string. Doing so leaves us with only x to read as we continue following transitions toward (maybe) an accept state.
We extended this idea by adding \varepsilon-transitions. In order to follow an edge labeled with \varepsilon while reading an input string w, we essentially remove the trivial prefix \varepsilon from w, leaving us with all of w to read as we continue following state transitions. In both cases, we’re removing a prefix of (what remains of) the input string before continuing on.
Why not extend the idea: Instead of only removing prefixes of length one or zero that match an edge’s label, we could label an edge with a string y of arbitrary length, indicating that in order to follow the edge, we need to remove the prefix y from the beginning of (what remains of) an input string yx, leaving us just x to read for future transitions.
We can take this idea even further: Instead of labeling edges with strings, we can label them with regular expressions. In order to following an edge marked with regular expression R, we have to remove from the input string a prefix matching R.
An expression automaton formalizes the idea. It consists of five components:
- The finite input alphabet \Sigma
- A finite set Q of states
- A unique start state s \in Q
- A unique target state t \in (Q \setminus \{s\})
- A transition function R: Q \times Q \to \var{Reg}(\Sigma). Here, \var{Reg}(\Sigma) denotes the set of regular expressions over \Sigma
The requirement that the target be unique and disjoint from s is done for the sake of making a clean “base case” in our algorithm.
We’ll stick with the informal idea of acceptance. An expression automaton M = (Q, \delta, s, t) reads in an input string by starting in state s and repeatedly following transitions p \to q for which R(p, q) matches a prefix of what remains of the input string. It removes the matching prefix and continue. If it ends up at t with no more of the input string to read, then it accepts, and otherwise, it rejects.
Now, suppose we are given an NFA M = (Q, \delta, s, A) with \varepsilon-transitions. We assume
- M has a unique accept state t with t \neq s and
- s \notin \delta(t, a) and t \notin \delta(s, a) for any symbol a \in \Sigma.
These conditions are easy to enforce by adding a new source and single accept state in addition to a few \varepsilon-transitions to any given NFA that does not meet them. We build an expression automaton M' = (Q, R, s, t) by setting R(p, q) equal to the union (sum) of all symbols and maybe \varepsilon for which there is a transition from p to q in M.
And now, we’ll repeatedly simplify M' until we can extract a regular expression that accepts the same language.
- If Q = \{s, t\}, then R(s, t) represents the language of M'. We’re done.
- Otherwise, let q be any state.
We remove it from M' and set R(p, r) to be R(p, r) + R(p, q)R(q, q)^*R(q, r).
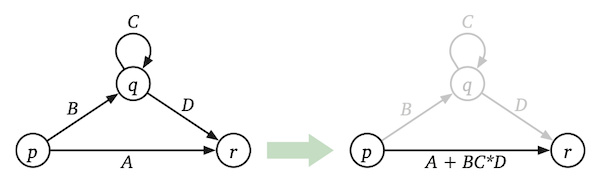
We remove one state each iteration, we the process has to eventually terminate with our new regular expression. We’re done! Do note, however, that the resulting regular expression could have size exponential in the original size of the input NFA.